Want to know The Truth About CPM?

02 September 2015

Stupid Programming Trick No. 25 part B – Hybrid Allocations the CDF Way

Pig Latin and Essbase

This series of Hybrid allocation approaches started out as a two part approach, but Peter Nitschke aka @essbasedownundr came up with a better way.  So, in the spirt of the before-there-was-a-Descartes-there-was-a-Caesar-or-a-horse is now in three or:
Hybrida Essbase prouinciis sunt divisa in partes tres, quarum unam incolunt file parsing alter CDF, tertiam qui ipsorum lingua Java nostrum BSO calc script appellantur. Haec inter se differunt secundum formam aditu codice, et complexionem.

Good stuff if you’re about to invade Gaul and make it a province of Rome.  And a good way to describe the three different ways of approaching Hybrid Essbase allocations.

Skip to the end (but absolutely Read The Whole Thing) for a translation into something a bit more understandable although I suspect you’ve guessed at the meaning.

And with that, heeeeeereee’s Peter!

The agony and the ecstasy

Upon first reading Cameron’s blog post on allocations in Hybrid I was horrified, disgusted, appalled, gobsmacked bemused regarding the machinations required to achieve something so simple. I believe there may have also been the words, “VBA??? That is the sound when doves cry.”, although to be honest I haven’t directly heard that but imagine that would be the sound of doves in their cognitive programming agony if they could code in VBA.  But I digress.  Surely, there is a better option!

Here are the issues to consider:
  1. All upper level members of a Hybrid cube are dynamic
  2. If we calculate against those upper members, we will throw the cube out of Hybrid mode. and into traditional BSO sparse dynamic calculations…at which point we’ll probably beat it in calculation using an abacus.  Or Roman numerals.  Or counting matchsticks.  You get the idea.  This is a Bad Thing To Be Avoided.
  3. Therefore we have to work out a method of getting the calculated upper level data to a stored level zero member.
  4. The only way to pull the data out at the upper level of a Hybrid cube is MDX.
  5. MDX is…not very elegant when run out using MAXL (hence Cameron’s everything-is-a-nail-if-VBA-is-your-hammer strategy).  Cameron notes that this analogy is applicable to screwdrivers, sledgehammers, and ODI when used to build Planning dimensions.

Back to the Future I – A history lesson

Okay – so the underlying problem is pretty simple. Let us now jump back to an earlier time, an easier time, a simpler time. Hyperion version 11.1.2.2. Before all of this Hybrid nonsense. When BSO cubes ruled the world and performance was lacklustre but we liked it that way.

One of the brand new and world-breaking features in 11.1.2.2 was the advent of the @XWRITE statement. The counterpoint to the @XREF – this would allow us to write data from one cube to the other and had some amazing potential! Its benefits were easily recognisable – because you were only writing from active blocks, performance was significantly increased, and @XWRITE also had one key advantage in its ability to create the blocks on load! Gone were the days on needing to put CREATENONMISSINGBLK above your @XREF statements and waiting hours.

One of the items slipped in the documentation for this function is as follows: “For @XWRITE only, a reserved keyword @LOOPBACK can be used to write to the same database.” Curious – but actually had some utility in its ability to create blocks. The very talented David Ambler turned this into an elegant strategy to create blocks for a balance sheet in future years – pushing opening balances from the closing balances of the prior year.

Now I bet I know what you’re all thinking – that’s great Peter, so you’re just going to use @XWRITE from the parent to write to the stored level-0 member. Well done for reusing a four year old function. Except...that doesn’t work. @XWRITE is one of those top-down formulas that doesn’t work in Hybrid (and I did try). The cube drops out of Hybrid mode and we’re back to the abacus.

Still it’s a nice idea. Use a function to write back to the database directly, rather than export the data, map it and reload it. Now all we need is a function that natively uses MDX.

Back to the Future II – Where’s my hoverboard

Fortunately Oracle has provided one! The new (from 11.1.2.3.502 at least) CDFs of MDXDataCopy & MDXDataExport. Perhaps even more fortunately, Celvin Kattookaran has already written up how it all works! (whom despite never having met, I feel indebted to a significant number of drinks for all of the assistance he’s provided over the years) .

So, we’ve got a function that can export data using MDX thus keeping the database in Hybrid mode as well as the ability to map data from one member to another.

Where it’s at

Using good ol’ Sample.Basic, albeit a Hybridized/bastardized version of it, the code is as follows:

//ESS_LOCALE English_UnitedStates.Latin1@Binary
RUNJAVA com.hyperion.calcmgr.common.cdf.MDXDataCopy
"whynotzoidbergasAESkey==" /* key */
"pemO6ZElxHY7m570TfvhDB8H4WMcxP53wjWPlB26SwETEj/so3WuzB8ZBjnJBhUJ" /*user*/
"nqkqpUXwhhAywRPnn/ZFxOy5kKpb7iZoZWf6bA1NOJVR1hBzj15k2hpzjcgIwidC" /* password */
"Hybrid" /* from application */
"Hybrid" /* from database */
"Hybrid" /* to application (can be the same as the source) */
"Hybrid" /* to database (can be the same as the source)*/
"{[Scenario].[Actual]}" /* MDX that defines the column members */
"crossjoin(crossjoin(crossjoin({[Year].Levels(0).Members},{[Measures].[Sales]}),{[Market].[Market]}),{[Product].[Product]})"  /* MDX that defines the row members */
"Sales,Market,Product" /* source member mappings, can be empty */
"Sales Driver,No Market,No Product" /* target member mappings, can be empty */
"" /* Target POV columns, members from dimensions that do not exist on the source*/
"-1" /* rows per page */
"e:\\Ifthisworkscameronowespeterabeer.log"; /* log file , can be empty */

Just one beer?  Surely more.  Alas, Americans only have Fosters, which is Australian for piss, so it’ll have to be an American microbrew .  Note that Australians are deeply ashamed of Fosters and wish that Castlemaine were on offer outside of Godzone so the world may understand the Awesomeness of Australian Beer.  Alas and alack, for unfathomable reasons it is not to be. Actually in truth: XXXX is Australian for piss. Fosters is merely Australian for Export Only. Still, it’s better than sex in a canoe.)

Breaking it Down

RUNJAVA com.hyperion.calcmgr.common.cdf.MDXDataCopy

Using the RUNJAVA command because we only want to run this command once and it’s all defined. There is also the function @CdfMDXDataCopy which could be used, but is not necessary here.

"whynotzoidbergasAESkey==" /* key */
"pemO6ZElxHY7m570TfvhDB8H4WMcxP53wjWPlB26SwETEj/so3WuzB8ZBjnJBhUJ" /*user*/
"nqkqpUXwhhAywRPnn/ZFxOy5kKpb7iZoZWf6bA1NOJVR1hBzj15k2hpzjcgIwidC" /* password */

This command requires a fully encrypted username and password and an associated AES key. In order to encrypt the key you need to use the calcmgrCmdLine.jar utility which can be found Essbase server. The command is as follows:
java -jar calcmgrCmdLine.jar -encrypt -key <key> <user>
java -jar calcmgrCmdLine.jar -encrypt -key <key> <password>

I had a number of problems with this because the error handling of the AES string length isn’t...great. Basically you need a 24 character key with enough entropy in it – it doesn’t actually matter what it is (see my example) but you’ll need to test a few options (or just hammer the keyboard to get 24 chars).

"Hybrid" /* from application */
"Hybrid" /* from database */
"Hybrid" /* to application (can be the same as the source) */
"Hybrid" /* to database (can be the same as the source)*/

This one is pretty self-explanatory. The standard use of this function is to write to other databases – but as you’ll see, you can replicate our @LoopBack function from earlier and write back to the source.

"{[Scenario].[Actual]}" /* MDX that defines the column members */
"Crossjoin(Crossjoin(Crossjoin({[Year].Levels(0).Members},{[Measures].[Sales]}),{[Market].[Market]}),{[Product].[Product]})"  /* MDX that defines the row members */

Okay: so this is one of the limitations of this process – the MDX query is simply a Column and Row definition. No Where clauses etc. Still, for what we’re trying to do here it’s reasonably functional.  

"Sales,Market,Product" /* source member mappings, can be empty */
"Sales Driver,No Market,No Product" /* target member mappings, can be empty */

Here is where some of the fanciness lies. Really simple mapping (it’s actually just a basic string replace function) but allows us to write from a parent to a child to move the data to a stored member.

"" /* Target POV columns, members from dimensions that do not exist on the source*/

This is blank because we have no additional dimensions (the target IS the source). However, this is potentially useful when you’re mapping to an ASO reporting with additional dimensions.

"-1" /* rows per page */

As described in the documentation – this is a function to allow for a limiter of queries. If it’s a positive number only the number of rows listed will be extracted from the source and mapped. Useful only if you’re concerned about an out-of-control MDX query. Setting it to -1 will extract and load everything (and is obviously recommended

"e:\\Ifthisworkscameronowespeterabeer.log"; /* log file, can be empty */

A log file that will be generated on the Essbase server. Incredibly useful for troubleshooting as it actually shows the processes and the outputs!

2015-08-28 10:09 >  Used Memory (Mb):8 Free Memory (Mb):237 Total Memory (Mb):245 Max Memory (Mb):245
Query:SELECT {[Scenario].[Actual]}on columns,crossjoin(crossjoin(crossjoin({[Year].Levels(0).Members},{[Measures].[Sales]}),{[Market].[Market]}),{[Product].[Product]}) on rows FROM Hybrid.Hybrid
User:admin
Source:Hybrid/Hybrid
Target:Hybrid/Hybrid
Rows Per Page:-1
Signed in User:admin
Grid Size: Rows(13) Cols(5)
                Actual   
Jan    Sales Driver    No Market    No Product    134590.0   
Feb    Sales Driver    No Market    No Product    130233.0   
Mar    Sales Driver    No Market    No Product    132922.0   
Apr    Sales Driver    No Market    No Product    128346.0   
May    Sales Driver    No Market    No Product    131673.0   
Jun    Sales Driver    No Market    No Product    135427.0   
Jul    Sales Driver    No Market    No Product    132977.0   
Aug    Sales Driver    No Market    No Product    137744.0   
Sep    Sales Driver    No Market    No Product    122903.0   
Oct    Sales Driver    No Market    No Product    127760.0   
Nov    Sales Driver    No Market    No Product    127837.0   
Dec    Sales Driver    No Market    No Product    130086.0   

Once you’ve got it working this should be set to missing for performance reasons.

So how’s it perform then?

On the topic of performance – how fast is it? On a fully loaded (admittedly a customised/hybridefied Sample.Basic) database of 9 dimensions with the biggest being 14k and 9k members and with the data logging turned on:
Total Calc Elapsed Time for [Test.csc] : [0.263] seconds
Without the data logging:
Total Calc Elapsed Time for [Test.csc] : [0.061] seconds

Given that you could put this step immediately after a data load (it’s Hybrid sonny – ain’t no aggregation time) that’s pretty ridiculous in an absolutely awesome way.

What have we learnt today boys and girls?

Four key takeaways from this:
  1. MDX is an awesome language – as long as you can work out a method of parsing it, or just not needing to.
  2. Hybrid is going to take some getting used to in order to come up new methods of calculating things
  3. Sree and his team in the Oracle Calculation Manager group are coming up with some fantastic CDFs to drive a whole stack of functionality going forward. Definitely worth looking at some of them if you haven’t already.
  4. Cameron really needs to step up his game ‘cos he ought to have figured this out on his own.

Okay, one more takeaway:  Latin may be a dead language, but when uttered by Caesar, it has a certain ring.  

In the Queen of Australia’s English

Hybrid Essbase allocations are divided into three parts, one of which is inhabited by file parsing, the other CDF, those who in their own language are Java, our BSO calc script, the third. All these differ with one another in the form of approach, code, and complexity.

The next, and last (unless someone else is disgusted by Cameron’s allocation code – there is always that chance) approach will be the far more pedestrian and frankly less exciting accumulation method but need every calculation incorporate a frisson of geeky awesomeness?  Sometimes boring is good.  And easy.  And BSO-only albeit within Hybrid.  It won’t be that bad.

Be seeing you.

24 August 2015

Stupid Programming Trick No. 25 part A – Hybrid allocations the Wild but Crazy way

Let’s talk about allocations of the most simple kind

Before I go any further, I must give credit to Tim German aka Cube Coder aka @CubeCoderDotCom. He and I came up with this approach as part of our Kscope15 presentation ASO, BSO, and Hybrid Calculations:  What’s Fastest, How Hard Is It, and Which One Should You Use?.  Never fear, this isn’t merely a rehash of that presentation as I go into quite a bit more detail in this post.  Also, this is the Fast, Cheap, & Out of Control straw man proposal.  The next post will be (hopefully) quite a bit more sane.

To set the stage, this allocation post will:
  • Use a Hybridized version of Sample.Basic
  • Allocate the indirect Budget cost Distribution from a pool amount
  • Use a driver based on Actual Sales level 0 Product and Market as a percentage of Actual Sales Total Product and Total Market

I (and the world+dog of Essbase developers) have written allocations like this since the Year Dot.  I purposely chose this example because it is so basic and yet pervasive.  Never underestimate how easy Essbase makes this sort of logic.  I think sometimes we lose track of the still-revolutionary functionality of Essbase.  But I digress for the eleventy billionth time in the life of this blog.

Danger, danger, danger

The title of this post contains “Wild and Crazy” and what I will show you will make your eyes pop out albeit not in a SNL 1970s Golden Age kind of way.  Nope, this one made my brain hurt when I wrote it.  I suppose that’s all a long way of saying that what I going to illustrate you works but you almost certainly should never, ever, ever use this technique.  Think of it as a laboratory experiment that shows an interesting approach but is impractical in the real world.  I have been burnt by too many other consultants’ “genius” to not want to touch this approach with a 40 foot barge pole and I don’t want you to go this way either.  

I write this post to illustrate how this could be done and only that.  And then to provide an approach to contrast in the next not-completely-insane-approach blog post.

You Have Been Warned.

But first what is the logic?

The goal is to allocate an indirect cost, in this case the Budget cost of distribution, to all level 0 Products and Markets.  Yes, this is Sample.Basic yet again, and why not?

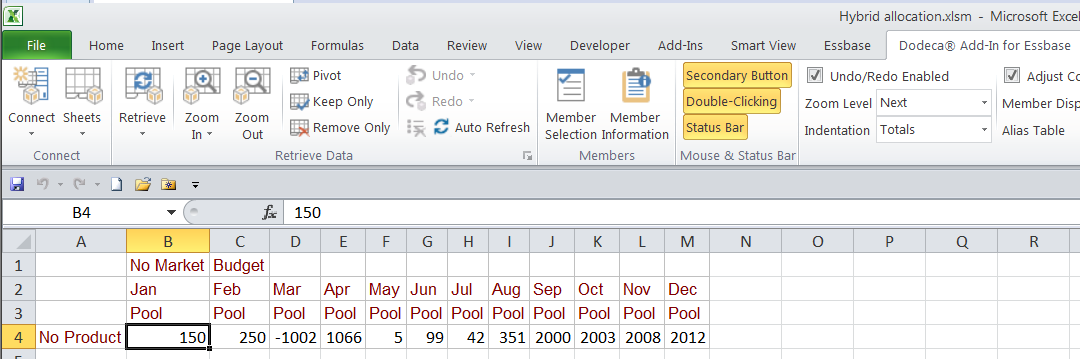
Expenses are entered at a level 0 in a pool member

The Budget data points to be allocated are at level 0 in each dimension. Note that No Market, No Product, and Pool are non-consolidating members specifically used to contain the data and not aggregate.

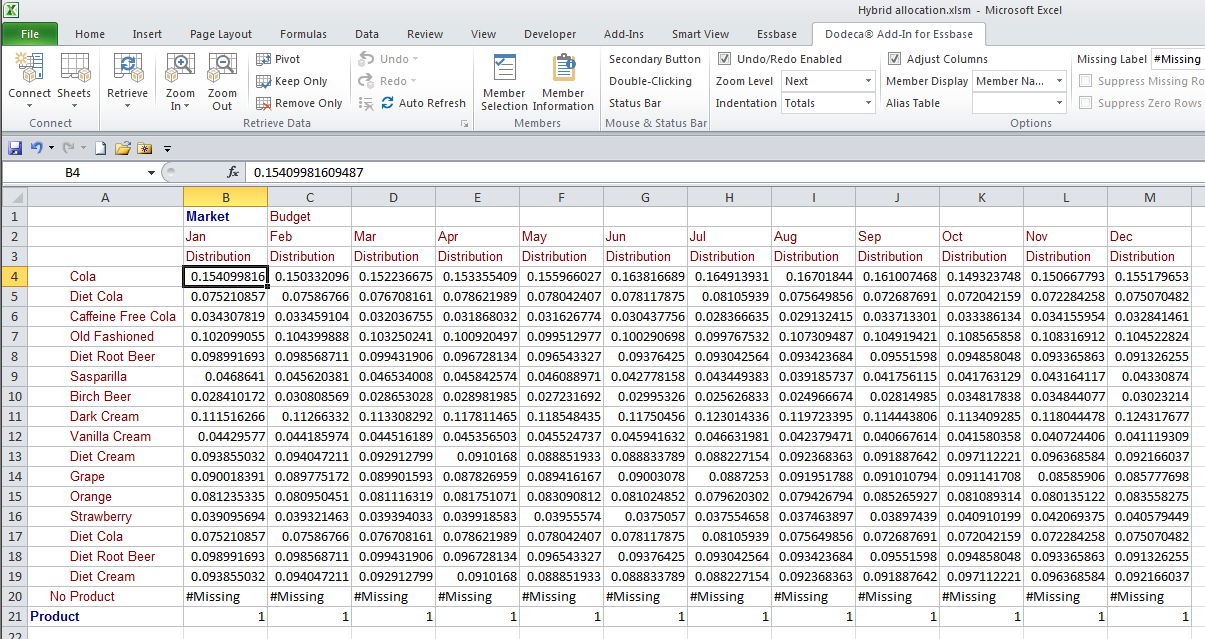
Calculate percentages

The allocation percentages are an interim step, normally never viewed.

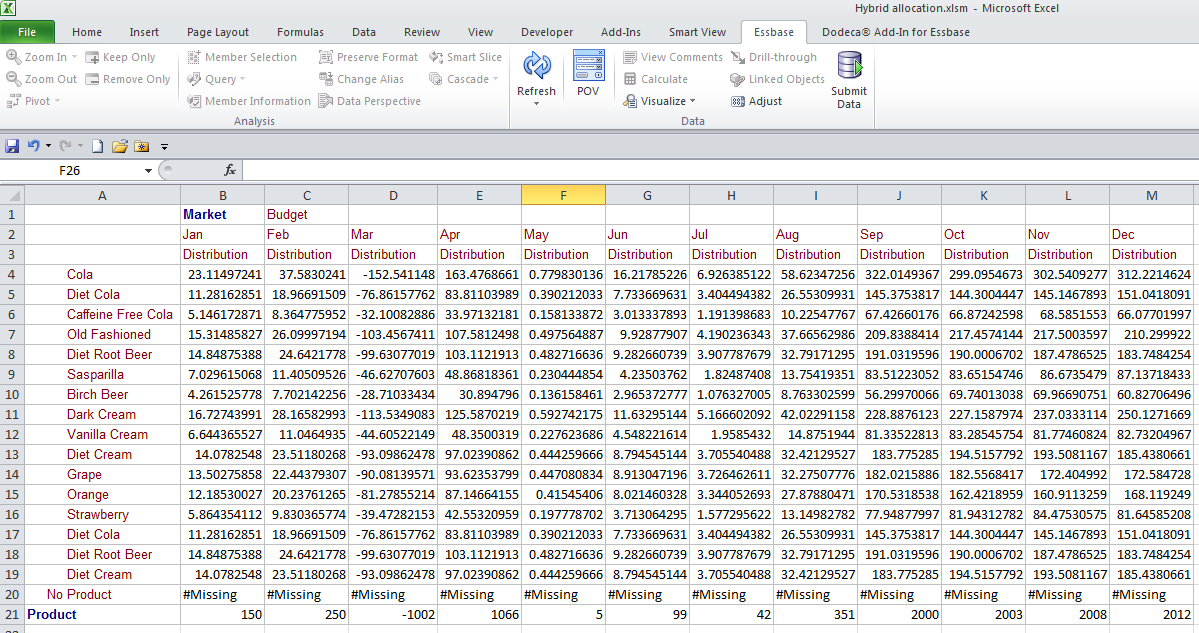
The allocated and aggregated results

Ta-da, Budget Distribution is now fully allocated.

With the logic out of the way, let’s delve into how this actually works across the various engines.

The BSO way

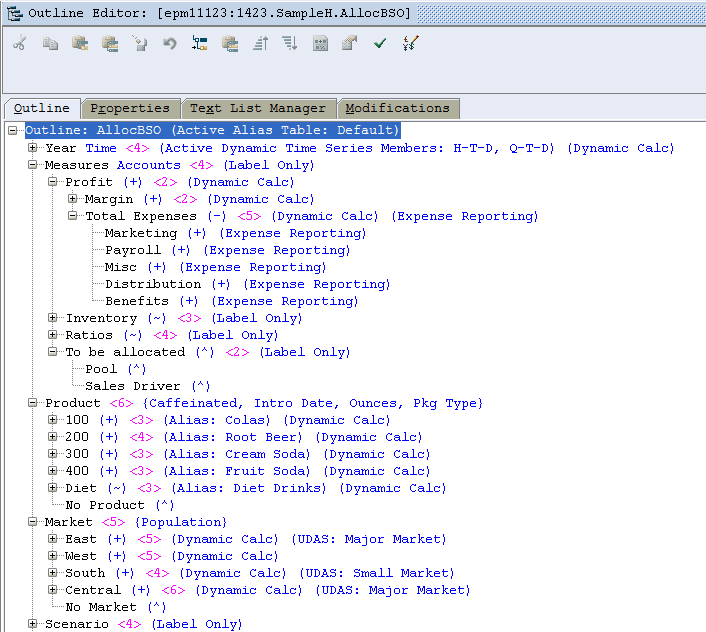
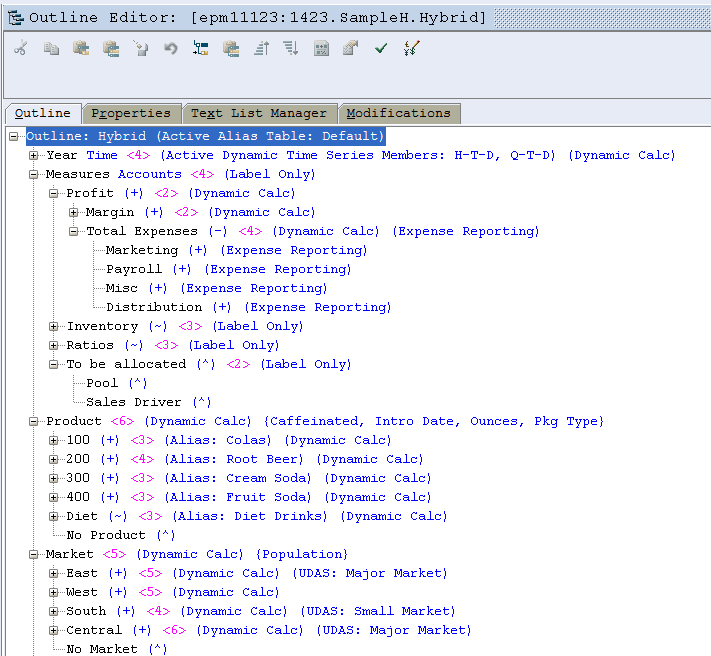
Outline

Surely you are familiar with this.  Certainly the readers of this blog are.

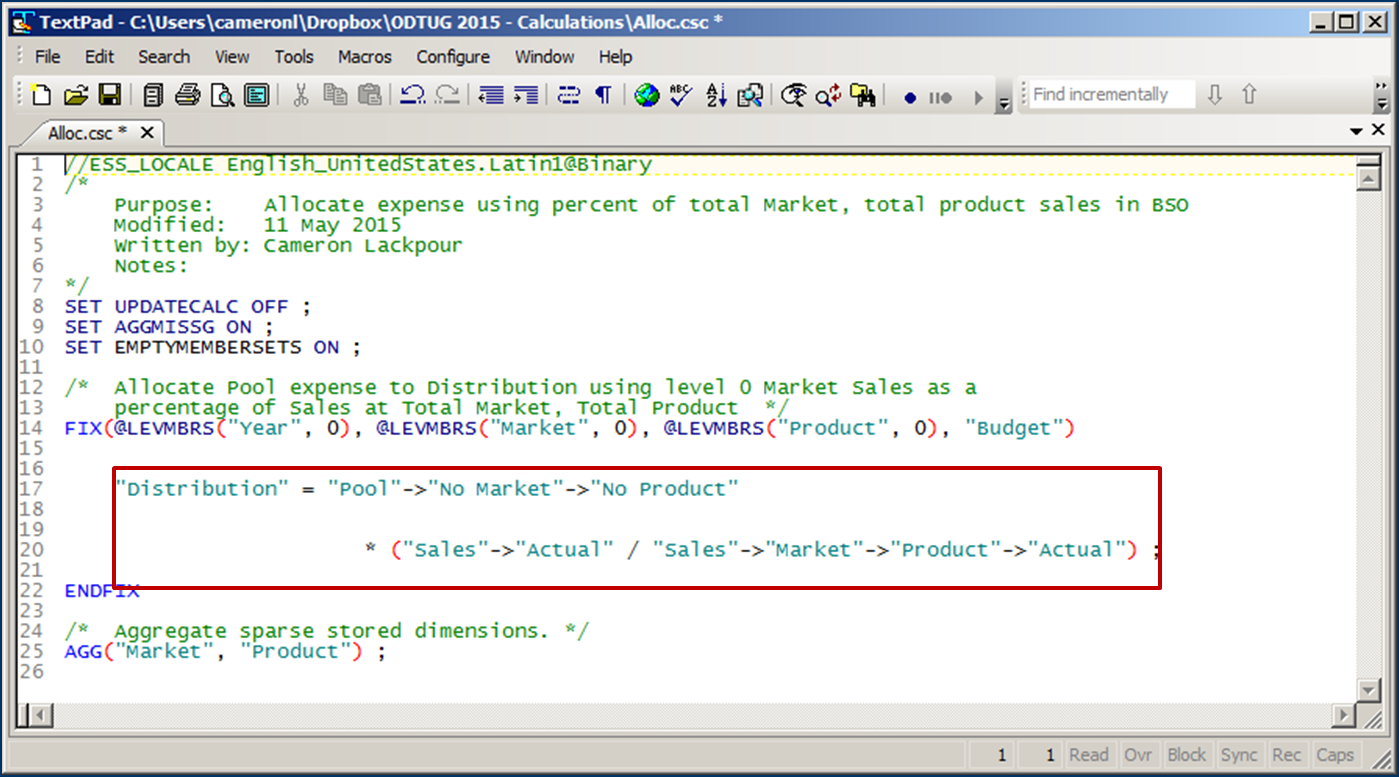
Assuming an already aggregated Sample.Basic, the code is as below.

Broadly, the code is as follows:
  1. FIX at level 0 Product and Market as well as period.
  2. use the percentage calculated from level 0 Product and Market sales divided by Actual Total Market and Total Sales.
  3. Aggregate the Market and Product dimensions.

As I wrote, easy peasy lemon squeezy.

The problem with Hybrid

Hybrid is great, Hybrid is fast, Hybrid is the best of BSO and ASO, Hybrid is the bee’s knees, Hybrid is the berries and yet at the same time, Hybrid sucks.  What?  Mr-OMG-I-love-Hybrid has a problem with the tool?  Actually, yes I do.  As Maxwell Smart would say, “Missed it by that much”.

What’s the problem?  The whole raison d’etre behind Hybrid is that it uses an ASO engine wherever dynamic sparse member calculations exist; those are then dynamically aggregate via ASO.  This gets around the the problem BSO has with scaling in the form of calculation time and disk space, the  gruesome-to-some MDX, and the opaqueness of ASO calculations scripts.  

Disk size isn’t much of a big deal today in the face of multi-terabyte hard drives (if this blog is around in five years, how we’ll all laugh at that as “big”) but a large collection of .PAG files is indicative of a long aggregation time; time is a constant as measured by us on Earth.  BSO’s genius is its retrieval speed (none of the engines beat it save for attributes) but its Achilles Heel is its inability to scale to larger databases.
If the ASO component of Hybrid is the solution to scaling, what’s the problem?  Those upper level Hybrid-enabled queries only work in a retrieval tool (Smart View, FR, etc.) and in MDX; FR only takes advantage of Hybrid if MDX is the retrieval language.  Where they don’t work is in calc scripts as of 11.1.2.4.  IOW, if you were to write a calc script that requires an upper level cross-dimensional reference that is retrieved via the Hybrid engine, i.e., just like this allocation process requires, the calc script will validate, and will work, but when that calc script refers to that upper level member, Hybrid reverts to true BSO sparse dynamic calculations.  This can be A Very Slow Thing (almost as long as that lovely run-on sentence above) and most certainly Something You Don’t Want.

As of 11.1.2.4.00x, there are only two ways to get ASO-drive Hybrid upper level data out of Essbase:
  • Run a query in Smart View/FR (again using MDX only)/etc.
  • Use MDX to get the data out – remember, neither DATAEXPORT or Essbase report scripts will export Hybrid upper level data.

I never promised you a rose garden when it comes to a clean approach.  This is a Stupid Hack after all.

What to do, what to do, what to do?

The answer is decidedly blue.  (If you’re not a fan of the American Songbook, and you clicked on the link to hear that, and you’re still not a fan of the American Songbook, there is really no hope for you.  And if you aren’t a fan of the Velvet Fog and King Cole, well, I’m so flabbergasted I can’t even rant about it.)   

It’s all in the wrist

The Stupid Trick is to load upper level data into level 0.  By that I mean: retrieve data from an upper level intersection and then load that data into a level 0 bucket.  Then when the allocation process occurs, the calculations are all level 0 BSO.  The beauty of this approach is that no aggregation (other than what Hybrid performs via its ASO engine) is required so in a budgeting scenario, the turnaround between  input and allocation and retrieval of the spread data should be very quick.

Peas in a pod

The only difference in the Hybrid world is the upper level sparse members.  Where they were stored in the BSO Sample.Basic in SampleH.Basic those members are set to dynamic calc.

Getting it out with a MDX crowbar

MDX is many things – powerful, flexible, a language with a fetish for parenthesis, square brackets, and curly braces – but one thing it is not is a good data extractor.  It works, but you’ll not be well pleased with the result.

Before I go into that particular rant – no worries, it’s coming – let’s take a look at this query.

Not that bad

I am, to be charitable, not very good at MDX but even yr. obt. svt. was able to figure this one out.

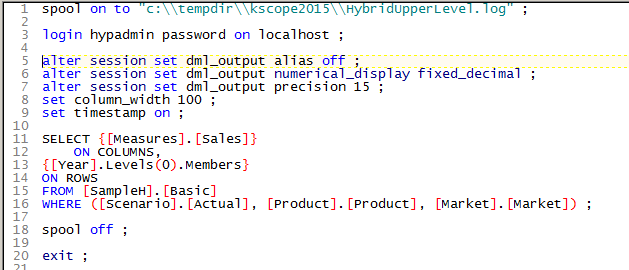
After setting display properties (and giving you my VM’s username and password), the query:
  1. Selects Sales
  2. Puts periods in the rows
  3. Restricts the retrieval to Actual, total Products, and total Market.

Quite bad, actually

If I had a $, £, ¢, R, etc. for every time I heard someone complain about MDX output over on Network54 I might not be a very rich man, but I’d at least be able to afford a better brand of Scotch.

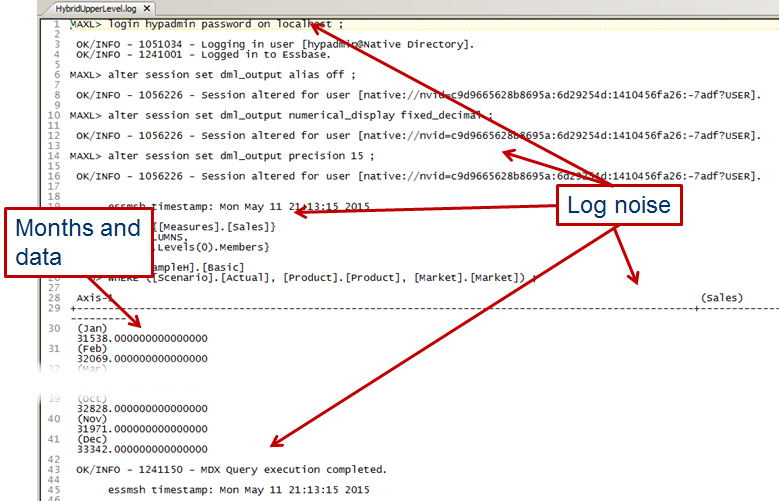
Look at this.  Lord love a duck, this is gruesome.  And the gruesomeness is about to get much worse.

I don’t want header information, or the query repeated in the spool file, or column headers, or query success messages.  This isn’t too much of a good thing, it’s just too much and most if that I don’t want.

I want doesn’t get

If Essbase is going to read the file it must be cleaned up and made fit for purpose via a parse of the file.  I am going to use a commonly used language in the EPM world – VBA in the form of VBScript to do so but as you will see it’s not an ideal tool.  Read it, marvel and its awfulness, and think about how you would do it in Perl or Groovy or Jython or just about anything else.

VBA est omnis divisa in partes tres


Unfortunately, I am not as pithy as Julius Caesar but I do my bit.  Also, I wish I taken Latin classes, Classical (not Demotic as that might actually be practical) Greek, and more than just a few courses in philosophy.  At least I get to be a singularly focused autodidact in practically every aspect of my life.  And have a job.

A fish rots from the head down

Per Microsoft,
A Windows script (*.wsf) file is a text document containing Extensible Markup Language (XML) code. It incorporates several features that offer you increased scripting flexibility. Because Windows script files are not engine-specific, they can contain script from any Windows Script compatible scripting engine. They act as a container.

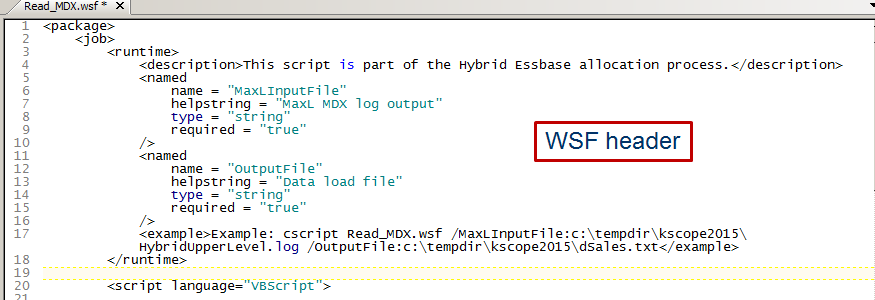
In the case of this script the header defines two required parameters:  the name of the MaxL file to be parsed and the name of the output text file.

‘Cos I can be a bit of stickler when it comes to code, I’ve included the optional <example> node.

Lastly, the script language, VBScript, is defined.

The Mystery Meat

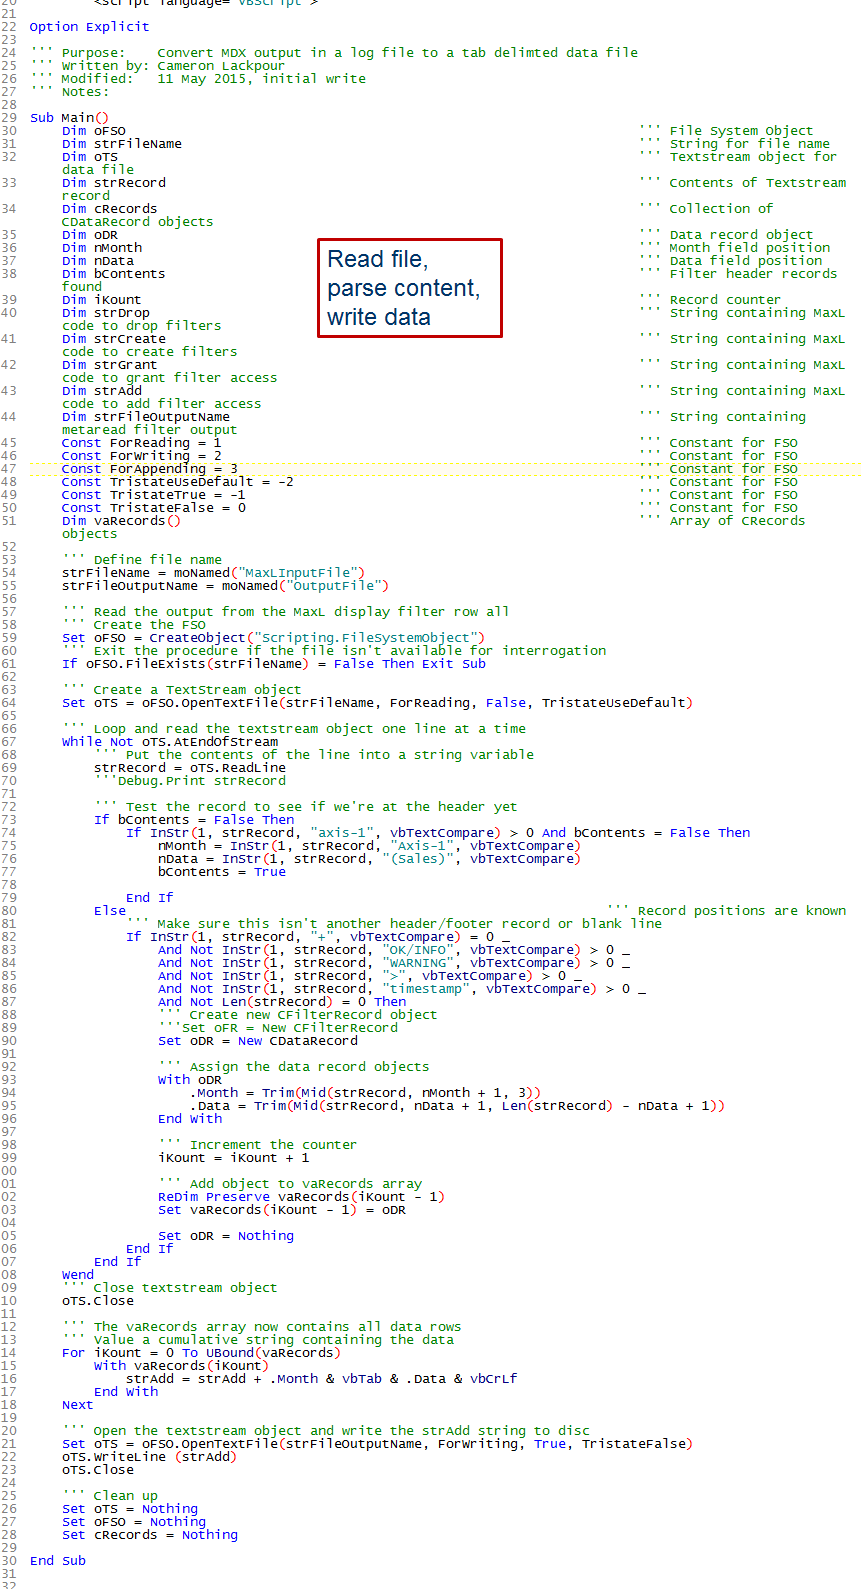
The MaxL MDX query output is beat-it-with-a-stick ugly.  So is this code albeit better formatted.  At least I destroy all of my instantiated objects at the end of the code.

Feet do your duty

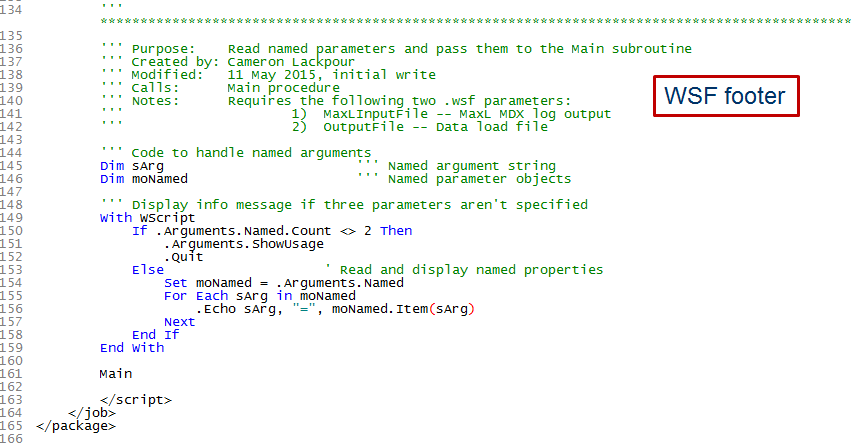
Interestingly (to some at least), the actual execution of the code is controlled at the end of the script.  Why?  Why not at the top?  Damfino.

In any case, the footer reads the arguments, ensures that they are valued, and then calls the Main procedure.

Call it names

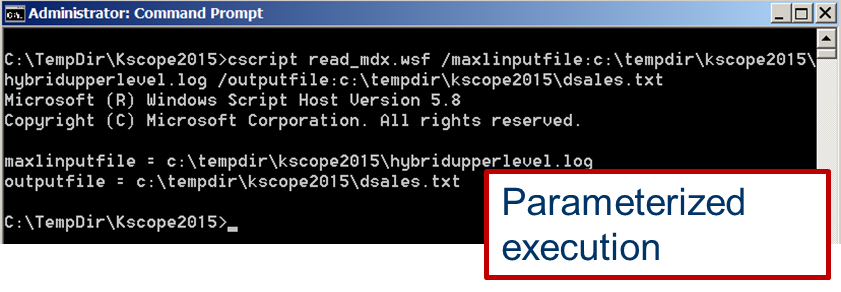
Running it isn’t so awful and once written, runs a treat.  I’ve even named the parameters and echo their values.  Ah, that pat on the back feels so good.

The output we’ve all been waiting for

An awful lot of pain for not much return.  At least it’s readable, although it still requires a tweak or two for Essbase.

But at least the stupid thing is readable by Essbase.  Almost.

Glenn, this is the moment you have been waiting for

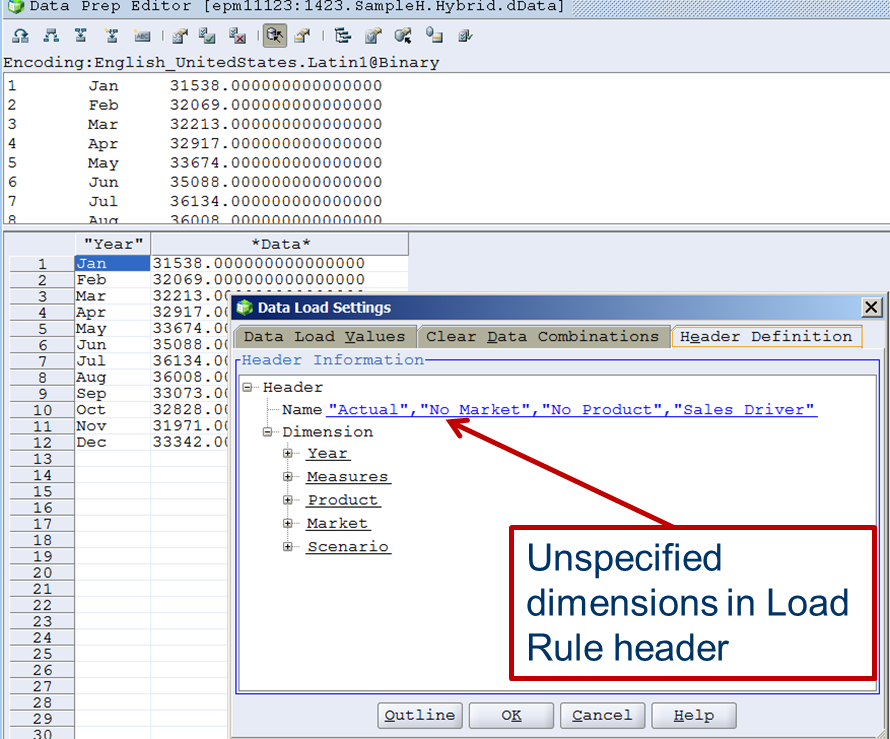
Does success taste best when served cold?  Yes, MMIC, I am going to use an Essbase Load Rule and I am going to use it to do ETL.  Oh the shame, oh the ignominy, oh the hack, oh the hypocrisy.  

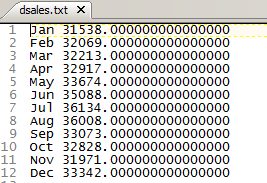
Yep, there it is – I’m hardcoding (gasp) the dimensions that aren’t defined in the from-the-Hell-of-MDX-query file to load those upper level members into level 0 buckets.

And now the calc

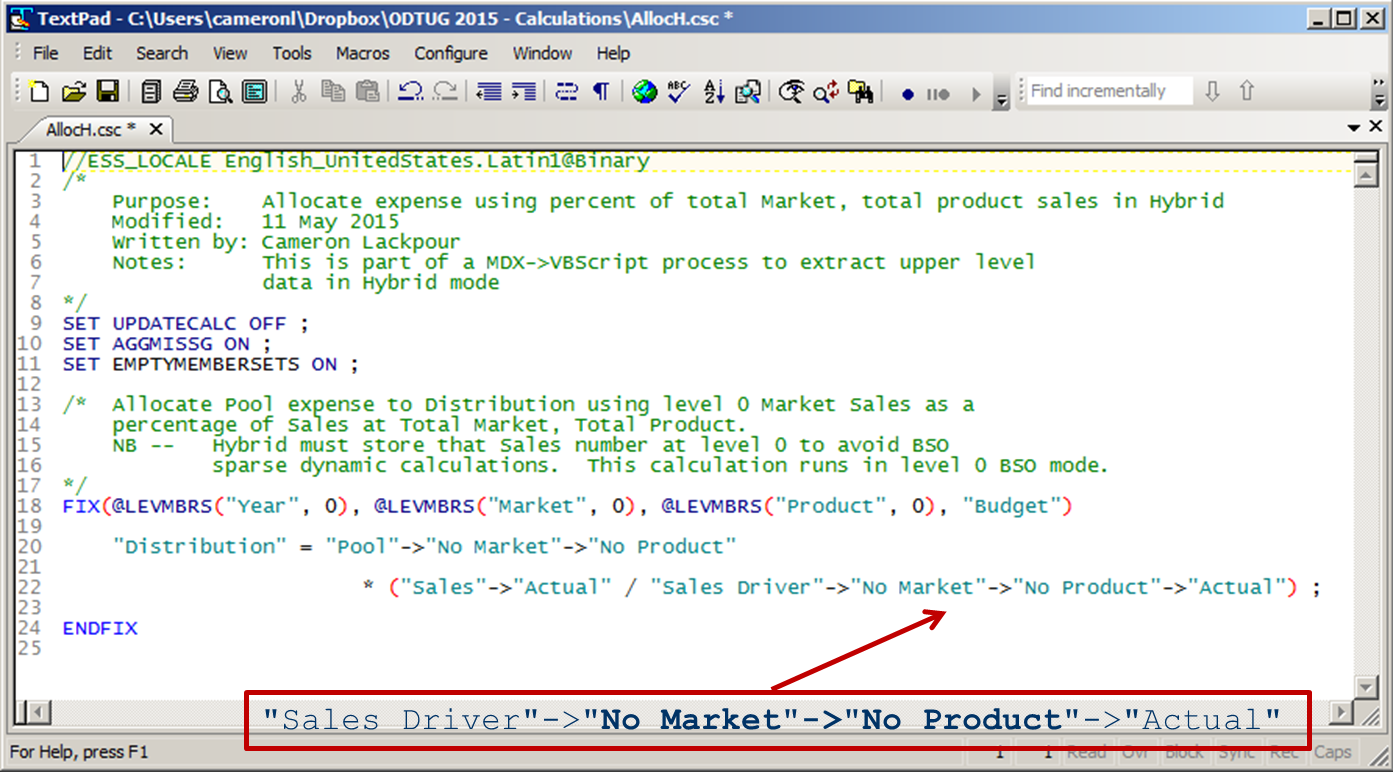
My oh my oh my we are finally here.  The upper level data from that MDX query has now been loaded to level 0 buckets and the allocation code – which looks almost exactly like the BSO code ‘cos that’s what it is – can use those totals to perform the allocation.

No aggregation is needed as this is Hybrid.  ASO on top of BSO is the dream come true.

Wot’ll she do, mister?

While all of this has been great fun, this level of complexity better be worth the candle.  Is it?  After all, Sample.Basic isn’t exactly a large database – there is no Slow with that wee beastie.

Using the same Essbase database that Tim German and I have used for the past two years – 40,000 customers against 70,000 products along with the typical Planning dimensions, the Hybrid numbers speak for themselves.
Engine
Performance in seconds
BSO
117
Hybrid
6

Yowsa.  Remember that 117 seconds assumes an already aggregated database.  So if there were to follow the typical Planning approach of enter, agg, allocate, agg we’re looking at something more like four minutes.  Four minutes vs. six seconds is an eternity when a business rule is run on form save.

In the Tree, part of the Tree

So is this the way forward?  Yes and no.

Is this fast?  Yes.

Will you ever use this particular approach?  No.  At least I hope so.

The next post in this Stupid Trick will show a much saner, much simpler, and much more likely approach to allocations in Hybrid.

Be seeing you.